
The LangWatch Blog
Engineering deep-dives, product updates, and field lessons on evaluating, testing, and observing AI agents in production.
Product Releases
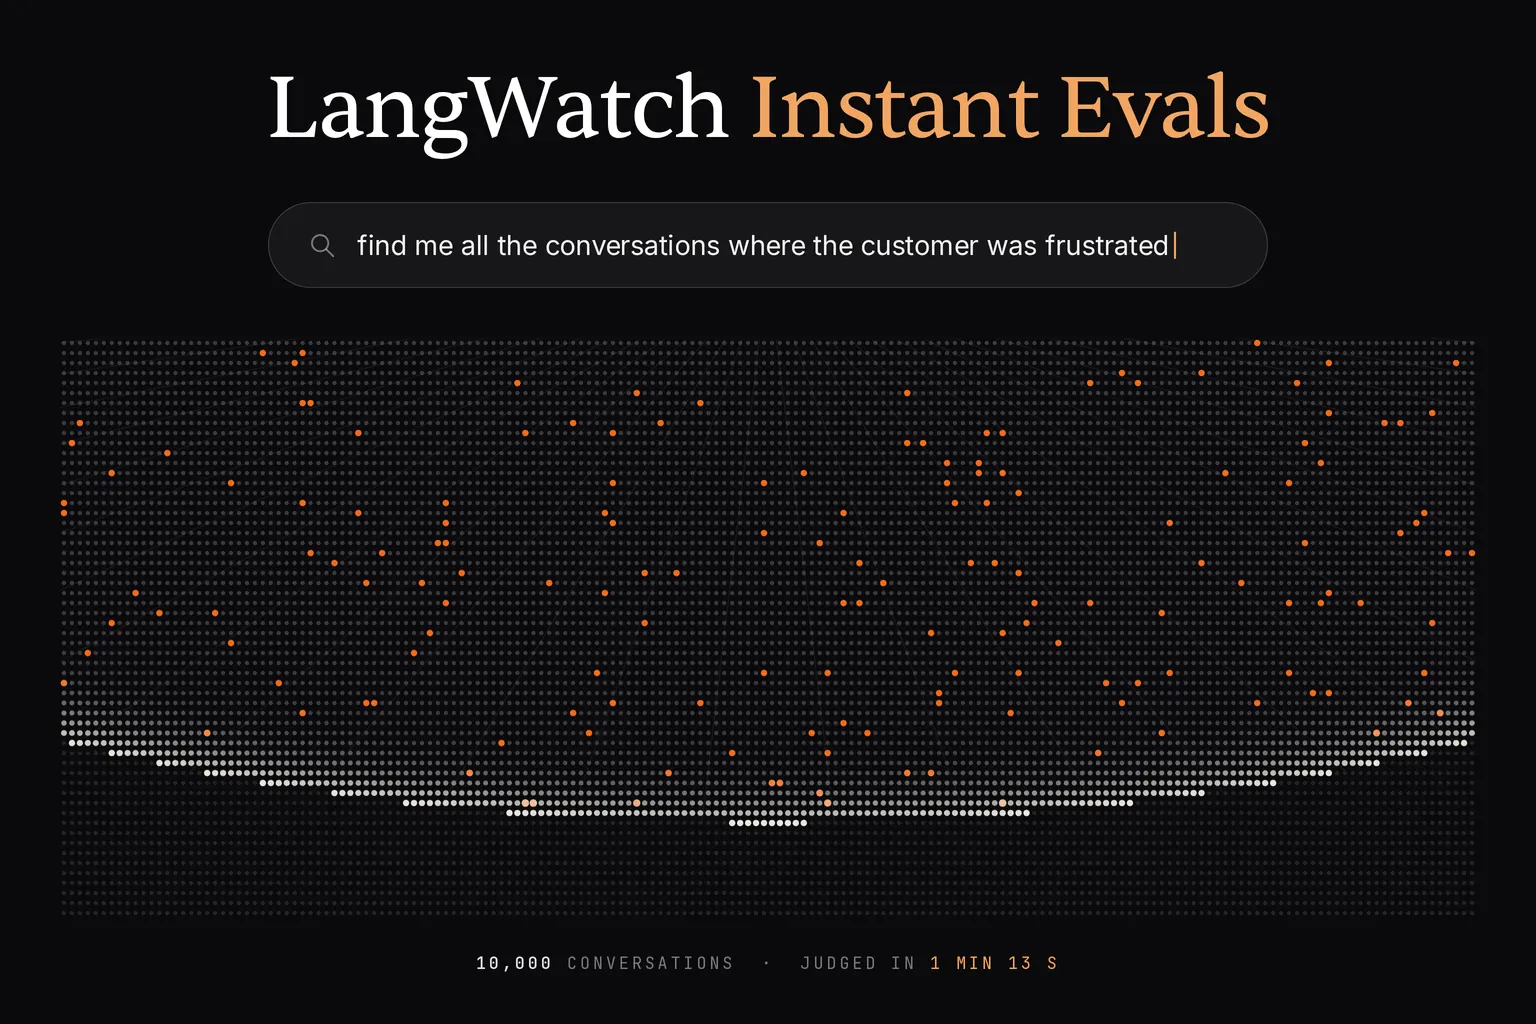
Introducing Instant Evals: evaluate your entire production history
Rogerio Chaves · September 22, 2026
Governance AI
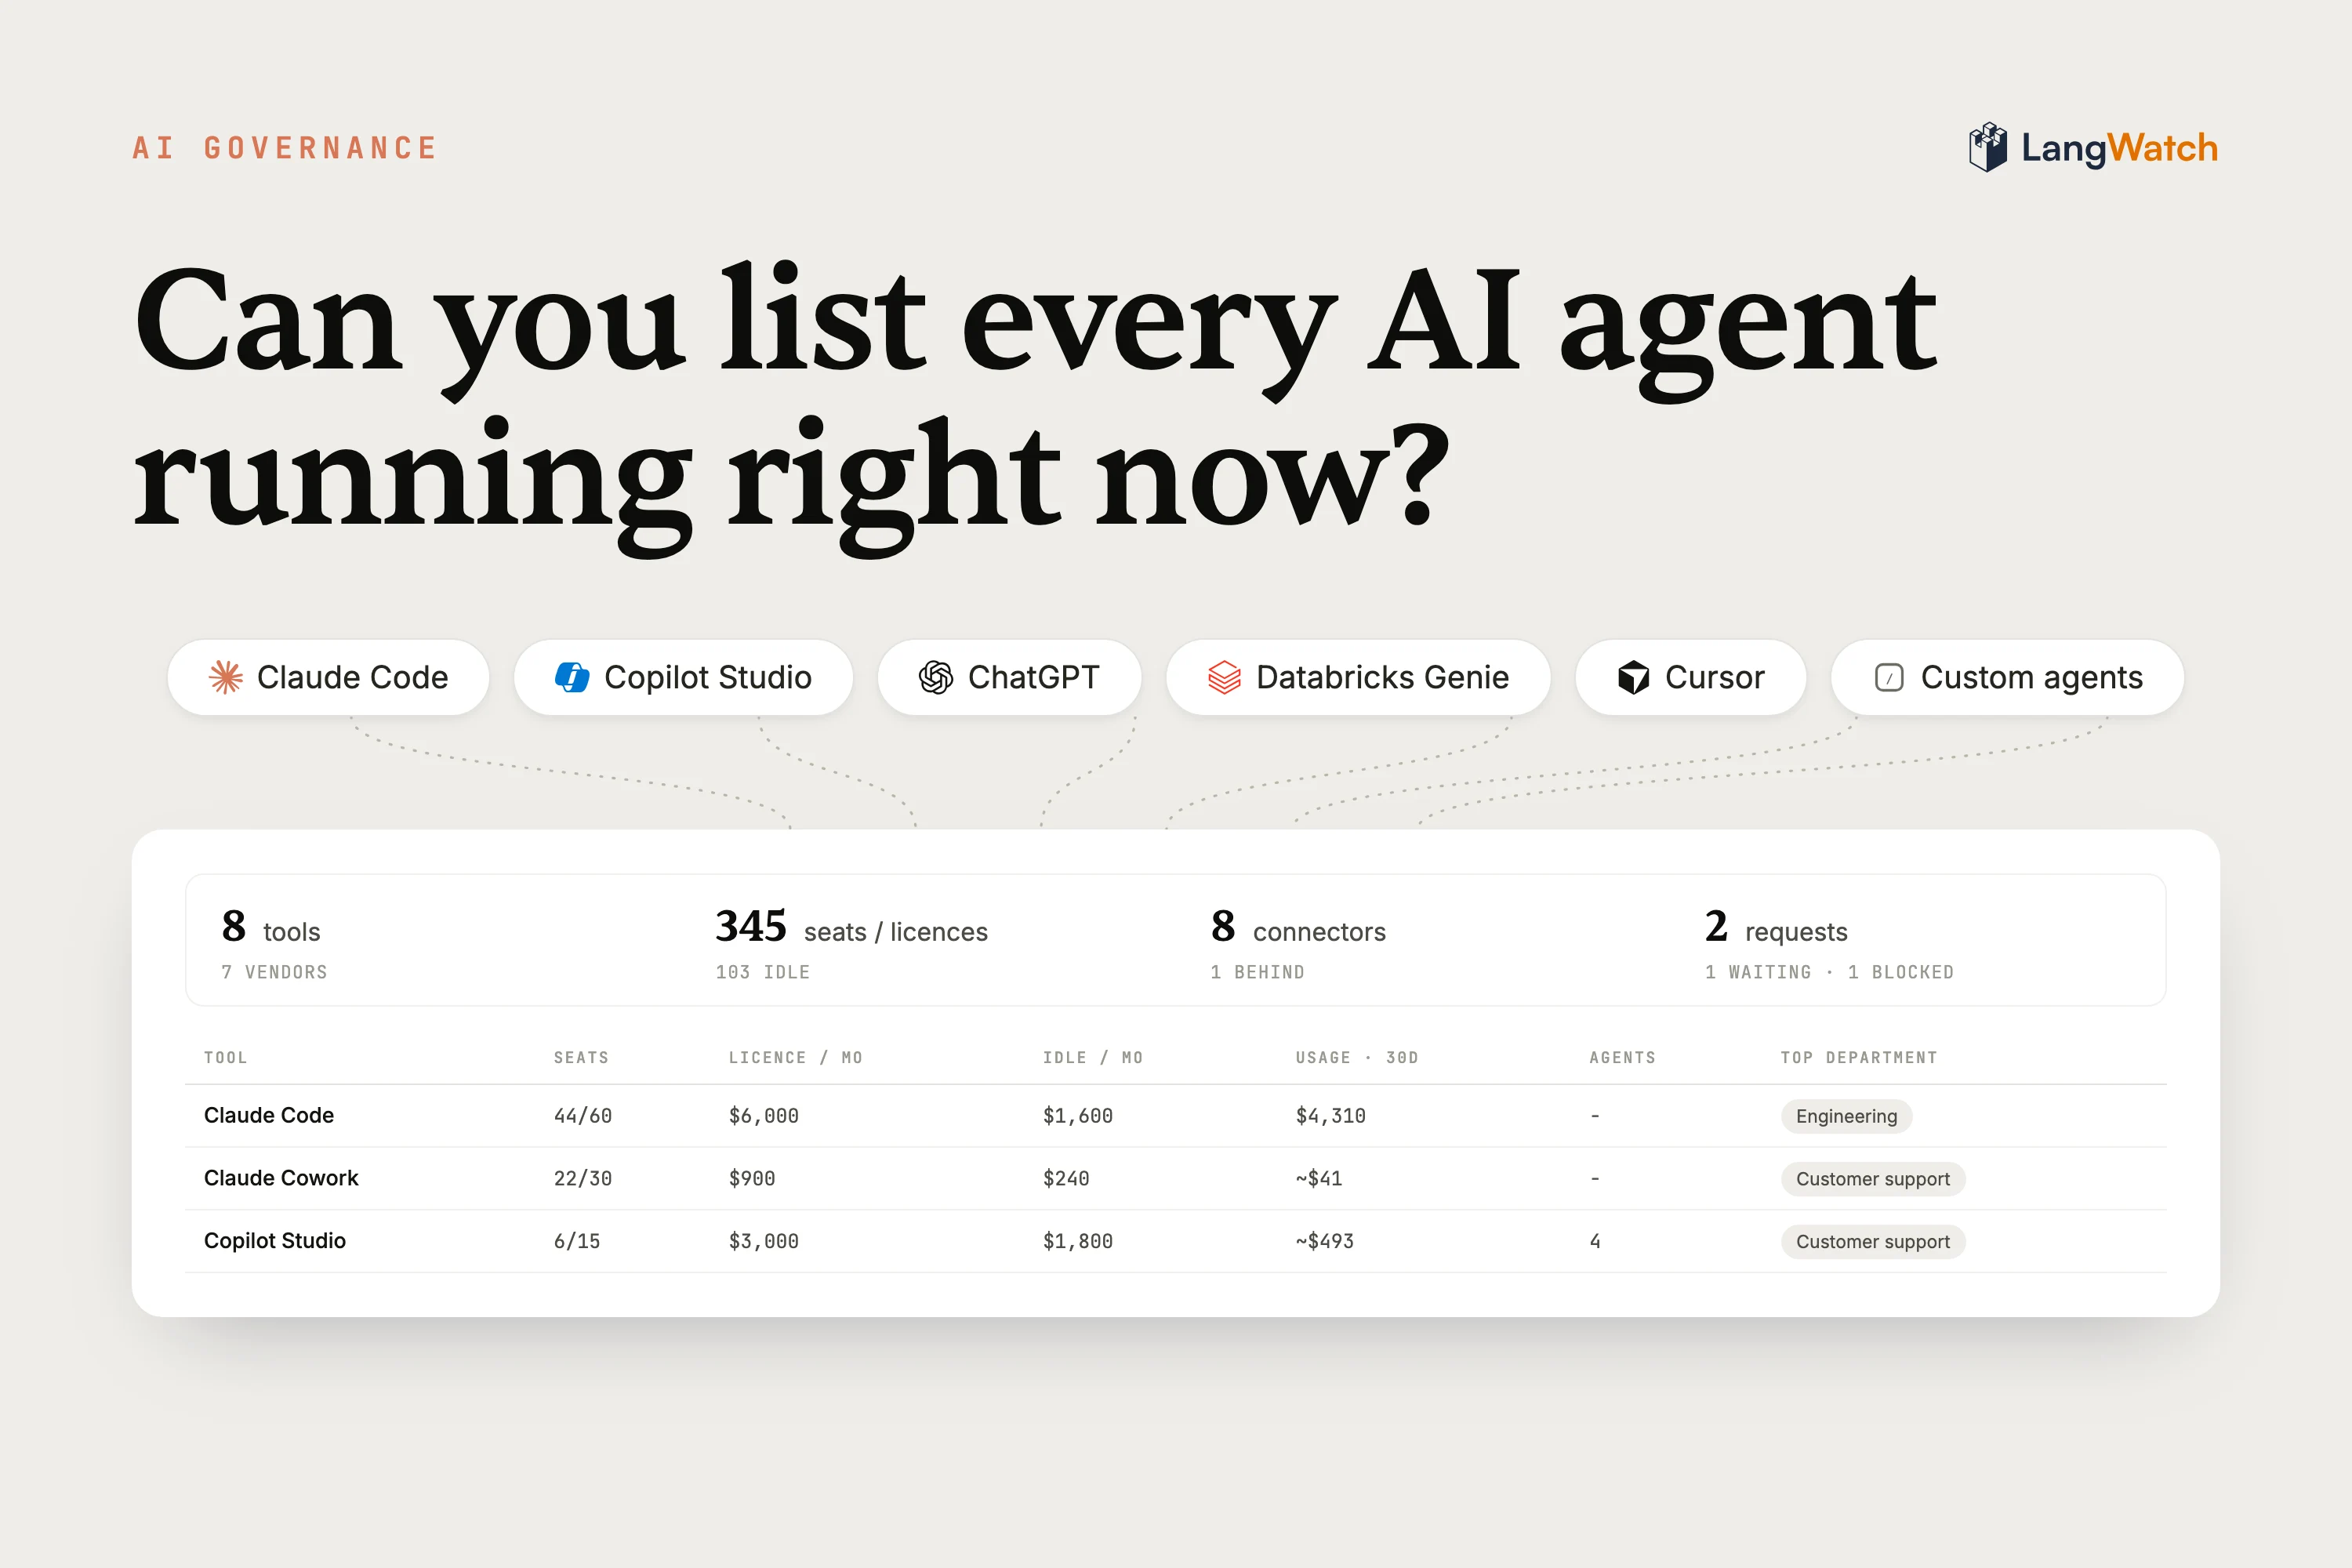
Can you list every AI agent running in your company right now?
Manouk Draisma · August 14, 2026
Governance AI
The 8 Best LLM Gateways in 2026: Compared for Production
Manouk Draisma · August 12, 2026
Integrations
One trace, two layers: OpenTelemetry between your LLM app and your cache
Every layer of the AI stack grew its own observability. Co-written with BetterDB: how cache decisions and LLM…
Manouk Draisma · August 12, 2026


Product Releases
Launching Claude Code usage tracking: see where your tokens go
Manouk Draisma · July 31, 2026
More from the blog

Getting to value with LangWatch, faster than ever - how to migrate from Langfuse to LangWatch with Skills.
LLM Evaluations Explained: Experiments, Online Evaluations, Guardrails, and when to use each in 2026
October 27, 2025Governance AIManouk Draisma & FlagSmith
How LangWatch helps enterprises test, evaluate, and trust their AI before release
Build vs Buy - Should you build your own LLMOps stack or leverage a purpose-built platform designed for enterprise scale?
The 6 Best LLM Evaluation Platforms in 2025: Why LangWatch redefines the category with Agent Testing (with Simulations)
Introducing the Evaluations Wizard: How to evaluate your LLM: Building an LLM evaluation framework that actually works
LangWatch vs. LangSmith vs. Braintrust vs. Langfuse: Choosing the Best LLM Evaluation & Monitoring Tool in 2025
LangWatch.ai - Announcing - €1M funding round to bring the power of Evaluations and Auto-Optimizations to AI teams.
OpenAI, Anthropic, Deepseek and other LLM Providers keep dropping prices: Should you host your own model?
December 20, 2024LLM EvalsCEO of HolidayHero - redated by Manouk
